Most AI infrastructure advice still assumes you want to rent someone else’s GPUs by the hour or fill a server rack with hardware you cannot lift. The FEVM FAEX1, a 3.3kg box roughly the size of a hardcover novel, makes both assumptions look outdated. With 128GB of unified LPDDR5X-8533 memory and an OCuLink port running full PCIe 4.0 x4, this mini PC can load a 70-billion-parameter model entirely in RAM and pipe out to a desktop-grade NVIDIA card for serious CUDA muscle. For teams running local inference behind a firewall, or developers who have watched cloud API costs eat their project budget alive, the appeal is immediate: one socket, no rack, no recurring bill.
Why Unified Memory Changes the Math
The FAEX1 runs AMD’s Ryzen AI Max+ 395, a 16-core chip with a 5.1GHz boost ceiling and 50 TOPS of NPU performance on XDNA 2. The memory architecture is the headline specification. CPU, integrated Radeon 8060S graphics, and NPU all draw from the same 128GB pool. For local LLMs, this eliminates the usual dance between system RAM and VRAM that kills performance on standard desktops. A model like Llama 3.1 70B or DeepSeek-R1 simply loads in full. There are no quantization tricks, no offloading layers to disk, and no watching token generation crawl because the system is paging.
The LPDDR5X-8533 speed also matters here. Memory bandwidth is often the hidden bottleneck in inference, and this setup moves data fast enough to keep the cores fed. Dual M.2 2280 slots accept up to 8TB of PCIe 4.0 storage for model weights and datasets. WiFi 7 and Bluetooth 5.4 handle peripheral connectivity without chewing port budget.
The OCuLink Pipeline to Serious Compute
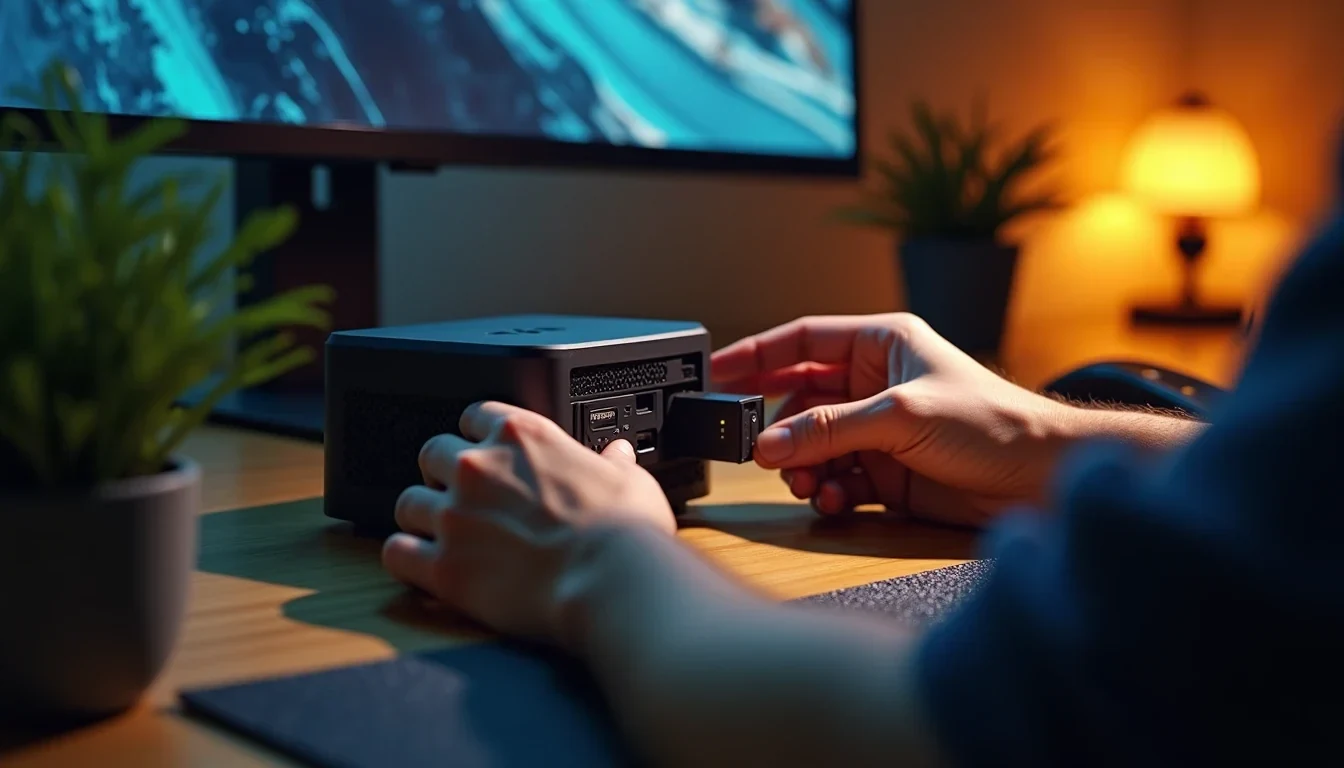
Integrated graphics will get you running, but the compact desktop hardware only becomes a genuine workstation when you attach external CUDA power. The FAEX1’s OCuLink port delivers a direct 8 GB/s bidirectional PCIe 4.0 x4 link to an eGPU dock. This bypasses the protocol overhead and bandwidth sharing that plague Thunderbolt or USB4 connections. For sustained 100% GPU loads, this raw pipe keeps data flowing without the stutters that can destabilise long training runs.
The recommended pairing is an open-frame eGPU enclosure, not a closed case. A 450W card running flat out generates serious heat, and enclosed housings throttle performance when consistency is needed. Docks like the Minisforum DEG1 or ADT-Link units expose the card to open air while anchoring the PCIe connection. The dual USB4 ports can host additional eGPUs for multi-card experiments, though at lower bandwidth per link than the dedicated OCuLink path.
What the RTX 4090 Actually Adds
Routing that PCIe lane to a MSI GeForce RTX 4090 Gaming X Trio 24GB changes the system’s personality entirely. The 24GB of GDDR6X VRAM handles model layers that exceed unified memory limits, while 16,384 CUDA cores and 512 fourth-generation Tensor Cores chew through matrix operations that would swamp the integrated silicon. The 384-bit memory bus pushing roughly 1TB/s of bandwidth keeps weight transfers from bottlenecking during batch inference. The 2520MHz boost clock extracts maximum throughput from the architecture.
This is not a gaming configuration dressed up for AI work. The 24GB frame buffer, the Tensor Core density, and the memory subsystem are purpose-built for the memory-bound, compute-intensive patterns of neural network execution. Connected over OCuLink rather than Thunderbolt, the card operates close to its native motherboard performance, not the diminished throughput that has made eGPU setups a compromise in the past.
The Real Cost for Local Buyers
AliExpress Global Shipping will deliver the FAEX1 to local addresses, but the landed price diverges sharply from the sticker. SARS flags shipments valued above roughly R25,000 to R30,000 for full customs assessment. Budget 15% VAT on the total declared value including freight, plus import duties of 0-7% depending on tariff classification, plus courier clearance fees. The practical rule is to add about 20% above list price before you have hardware in hand.
At current pricing, the RTX 4090 adds approximately R47,999 to the build. Total system cost pushes toward R200,000 once everything clears customs. That is serious money, but the comparison point is not a gaming PC. Enterprise GPU servers with comparable memory capacity and compute throughput start well above this figure, require rack mounting, and assume ongoing facilities costs that do not appear on the invoice. For a development team or small business that needs local model hosting without cloud dependency, the compact footprint and single-socket power draw represent a different cost category entirely.
Networking for Scale
The Realtek 8125BG 10GbE port is easy to overlook on a mini PC, but it makes this build more than a standalone toy. At ten times standard Gigabit speed, it supports clustering multiple FAEX1 units for distributed inference or training. Model synchronization and dataset shuffling do not stall waiting on the network pipe. For high-performance NAS connections, the same bandwidth loads training data or writes checkpoint files without becoming the bottleneck that wastes GPU cycles.
Three USB 3.2 Gen 2 ports, two USB 2.0 connections, HDMI 2.1 and DisplayPort 1.4 outputs, plus dual USB4 Type-C ports with 100W power delivery, cover peripheral and display needs without adapters. A physical performance mode switch and fan lighting control round out a chassis that is deliberately utilitarian, not minimalist for its own sake.
Who This Setup Actually Serves
The FAEX1 plus RTX 4090 combination is not for everyone. Cloud inference remains cheaper for intermittent usage, and a standard desktop with 64GB RAM suffices for smaller models. This build targets teams with persistent local workloads, data residency requirements, or API cost trajectories that have become unsustainable. The 128GB unified memory handles model sizes that force most workstations to compromise. The OCuLink path to desktop CUDA closes the performance gap with rack servers that demand dedicated space and cooling infrastructure.
For roughly R200,000 all-in, you get a 3.3kg base unit that fits on a desk, loads 70B parameters without swapping, and pipes to 24GB of GDDR6X when the workload demands it. The weapons-grade description is marketing speak, but the underlying capability is real: local LLM hosting at scale, no rack required, no meter running in someone else’s data centre.